How to Write a Data Scientist Resume in 2026 (With an Example)
This guide shows you how to write a data scientist resume before you have the job title. You'll get a bullet formula that works without business results, a way to present your projects, and advice for moving in from another job.
If that sounds like a lot to fit on one page, it is. You might be starting with a decent set of skills and a nagging feeling that none of it looks like "real" experience yet.
That feeling is worth taking seriously, because a hiring team often judges your projects by the one page that describes them. A good project with a vague line under it can lose to a smaller project described well.
By the end, you'll have one complete annotated resume to work from. Every claim on it is one you could explain in an interview, and that turns out to be the test that matters most.
Table of Contents
- What Hiring Teams Look For on a Data Scientist Resume
- How to Order Your Resume Sections
- How to Format a Data Scientist Resume
- How to Write Data Scientist Resume Bullets
- How to List Your Technical Skills
- How to Present a Data Science Project
- How to Tailor Your Resume to the Role
- Moving Into Data Science From Another Job
- Education, Certifications, and Extras
- A Complete Entry-Level Data Scientist Resume Example
- Common Data Scientist Resume Mistakes
- What to Do Next
- Frequently Asked Questions
What Hiring Teams Look For on a Data Scientist Resume
Before you write a single line, it helps to picture where your resume actually goes after you click "submit." It's often checked twice before anyone calls you.
First, an applicant tracking system (ATS) may scan it for the skills named in the job posting. Then a recruiter or hiring manager reads it, usually quickly, and often with a long list of other applications waiting.
Most large employers use one of these systems. Jobscan detected an ATS at 97.4% of Fortune 500 companies in 2026. So if you've ever wondered whether a piece of software reads your resume before a person does, at a large company the answer is very likely yes.
The human read is fast too. In a 2018 eye-tracking study by Ladders, recruiters spent an average of 7.4 seconds on their first look at a resume.
Seven seconds can feel unfair when you've spent months building skills. But those seconds decide whether you get a closer look, not whether you get the job, so your page only has to earn that second read.
Stephen Yu runs the consulting firm Willow Data Strategy. He described the same habit in an earlier interview for this guide:
"Let me be honest. Before I meet somebody, I spend less than 30 seconds. If that resume doesn't speak to me, which only happens with one in ten resumes anyway, I'm not even going to call the candidate."
The two readers look for different things, and it's useful to see them side by side:
| What an ATS checks | What a hiring manager checks |
|---|---|
| The exact skill names from the posting | Whether each project answers a real question |
| Job titles and dates it can read | Whether results are compared with a baseline |
| A single column it can scan in order | Whether the GitHub link opens to a README |
| Standard section headings it recognizes | Whether you could explain each number |
| A file type it can open | Whether your tools match the team's |
Notice that the left column is mostly about format, and the right column is mostly about trust. The software wants to read you. The person wants to believe you.
That second part has become harder. In a Robert Half survey from March 2026, 65% of hiring managers said skills are now harder to verify. They pointed to a surge in applications, many written or polished with AI.
In Resume Genius's 2026 hiring survey, 80% of hiring managers said they can often tell when AI wrote a resume.
You can treat those numbers as bad news, or you can treat them as an opening. When every other application sounds polished and vague, a page that's quick to check stands out, because it gives a busy reviewer a reason to trust it.
In practice that means named tools, named datasets, results you can explain, and a repo link that opens. The rest of this guide shows you how to build each one.
To see which skills to lead with, look at the skills employers ask for at each level in our data scientist job description guide.
How to Order Your Resume Sections
Section order sounds like a small decision, but a reviewer reads from the top and forms an opinion before reaching the bottom.
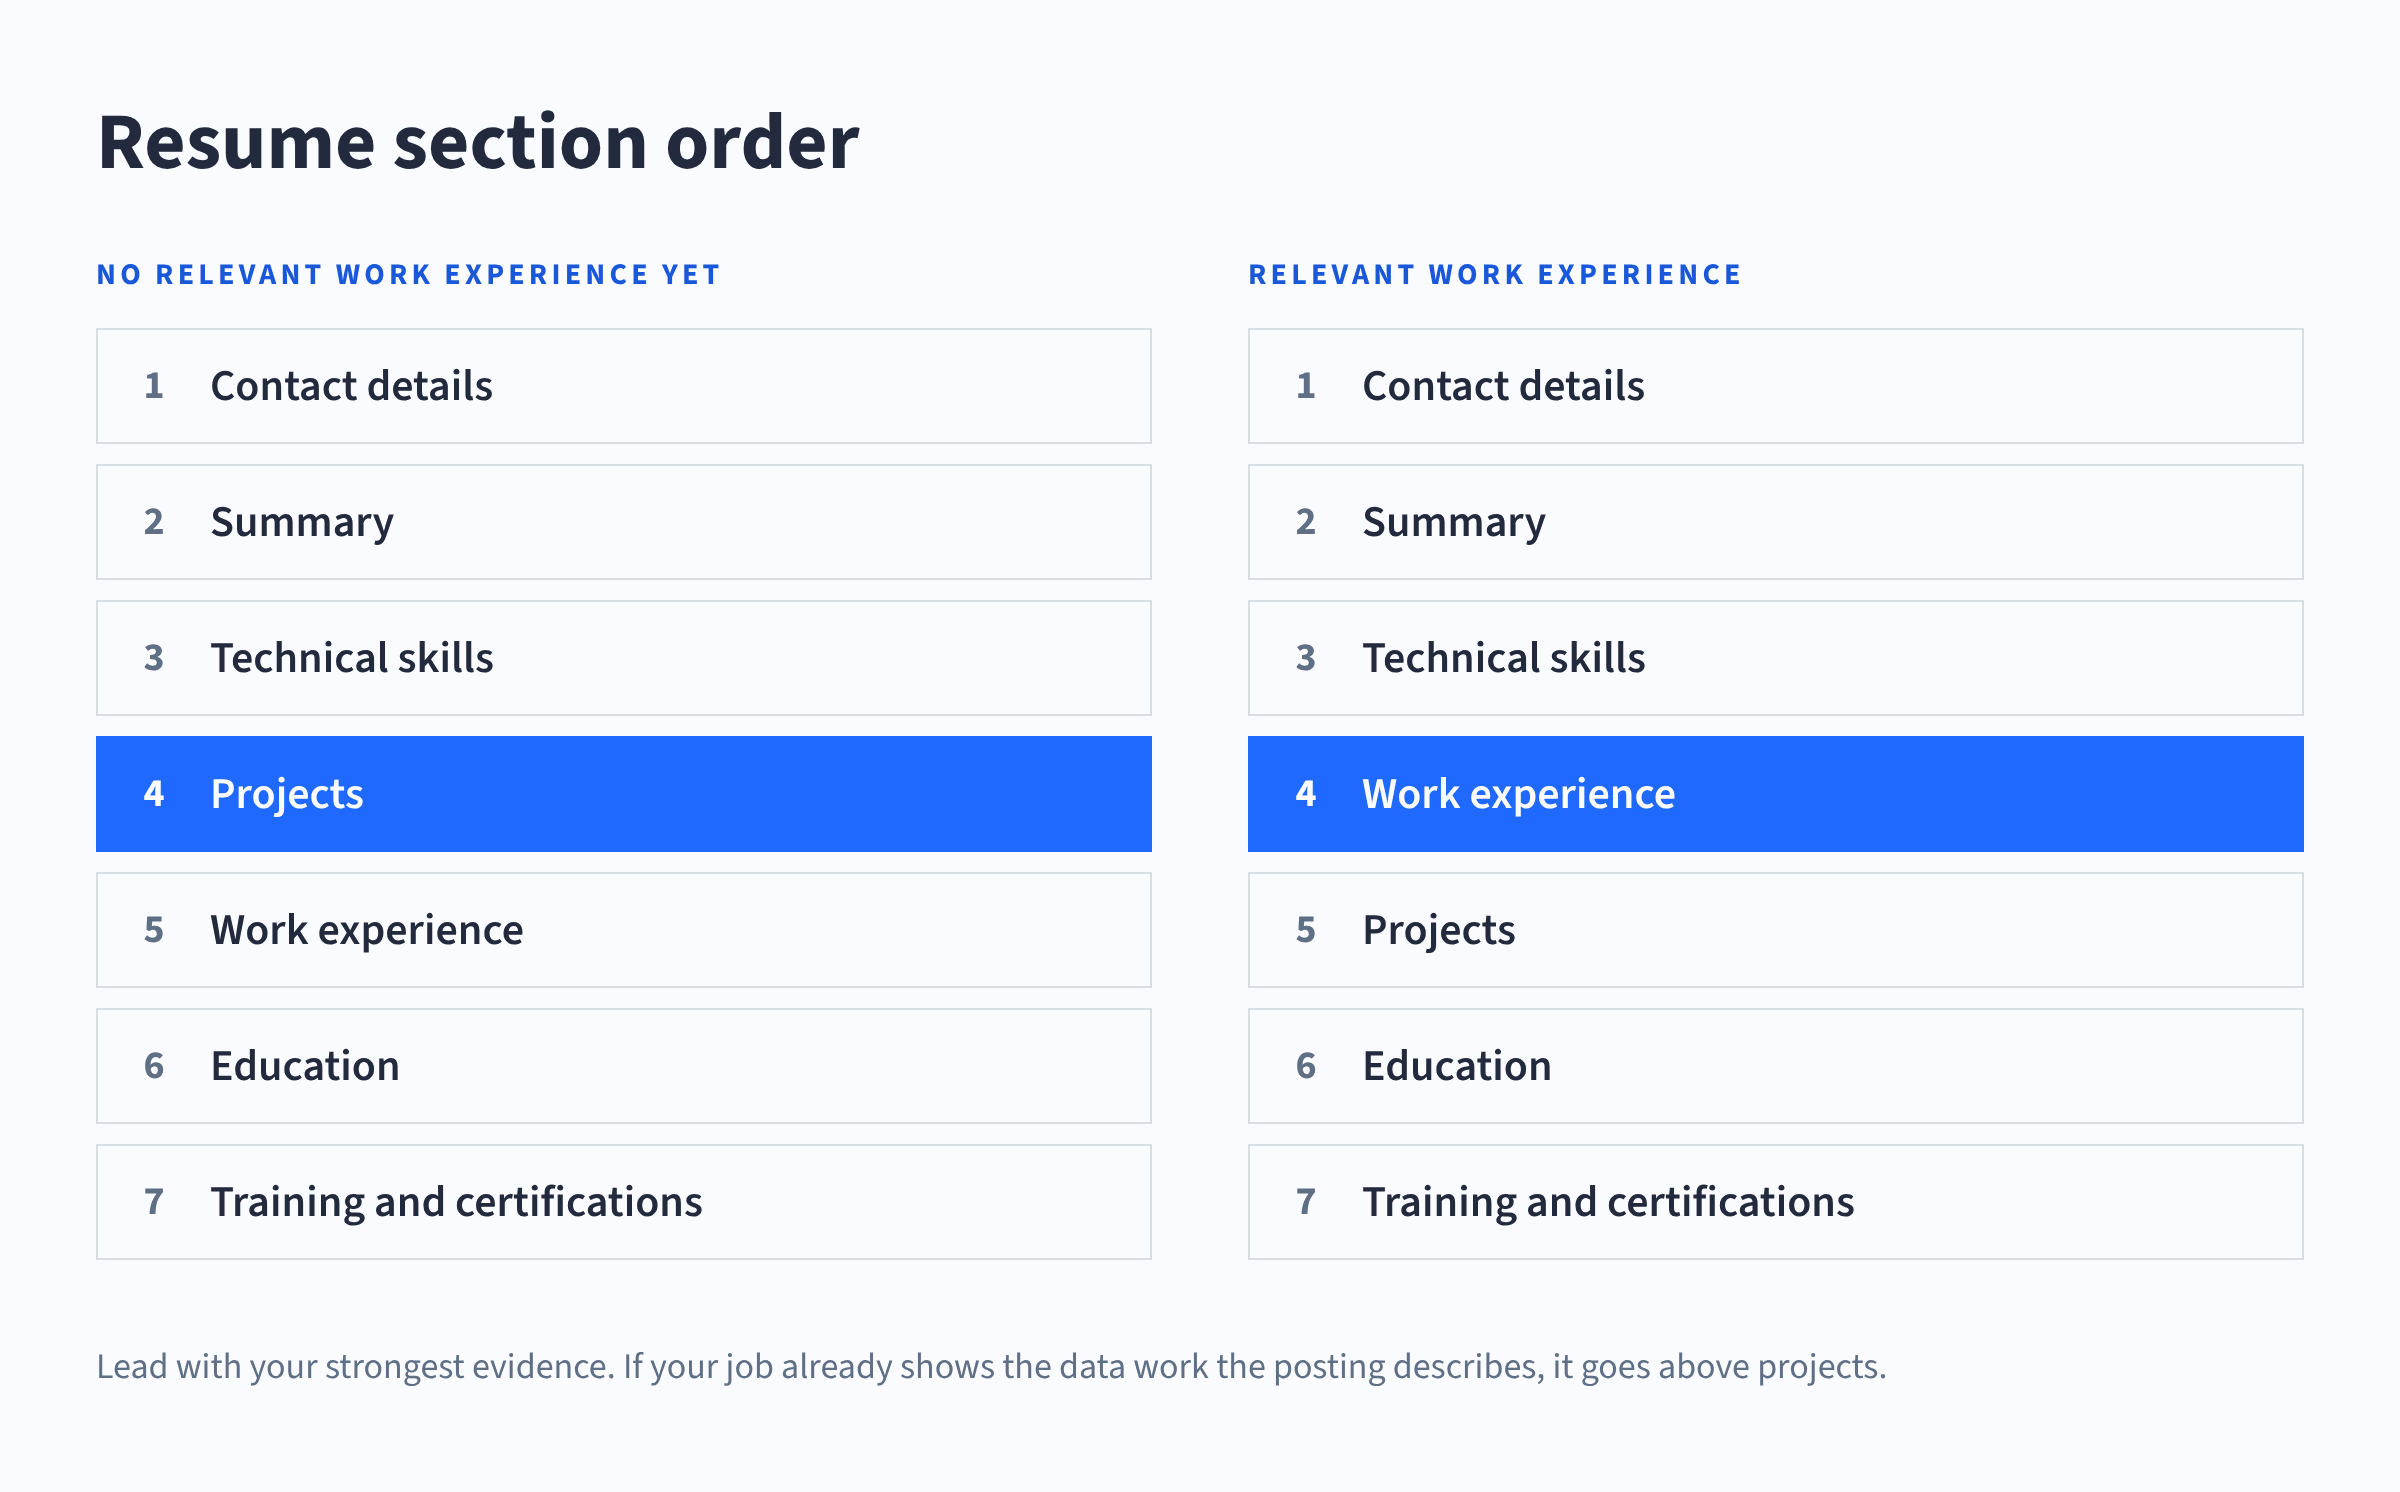
The order that works for most people starts with skills, then puts your strongest data science evidence next. Here's the order to use if your work history doesn't show data science work yet:
- Contact details
- Summary
- Technical skills
- Projects
- Work experience
- Education
- Training and certifications
Technical skills go near the top because recruiters and applicant tracking systems scan first for the skills in the posting. Put them where both readers look first.
Projects and work experience are the decision that matters. If you already have relevant experience, meaning a job where you did the kind of data work the posting describes, it goes first. Otherwise, projects go first.
Why: a reviewer should meet your strongest evidence before anything else. If they read an unrelated job first, they may decide you're not a fit before they see what you've built. If your job already shows that evidence, moving it down would hide your best material.
Many resume templates list education first. But if you've got work experience and/or relevant projects to showcase, you'll want to show those off first and put education closer to the bottom.
This order isn't permanent. As your job starts to include more data science work, experience moves up, and projects become the supporting act.
Your summary is the one place where you frame everything below it. Use two or three lines to say what you build and the kind of role you want.
Skip words like passionate and detail-oriented. They're the first words that come to mind, and they give a reviewer nothing to check. "Build classification models in Python and compare every result with a baseline" says more in the same space.
If your skills section looks thin, more learning will help more than better wording. That's an uncomfortable thing to hear when you want to apply this week, but no phrasing can stand in for a skill you haven't used yet.
Our Data Scientist in Python path teaches Python, SQL, statistics, and machine learning through 27 projects you can extend and add to your resume.
How to Format a Data Scientist Resume
Formatting is the least exciting part of a resume, and it's also where a good application can quietly fail. A few choices decide whether your resume reaches a person at all.
- Keep it to one page. Condense your experience to the most important, most relevant points so it's easy to scan. A two-page resume with no data science job history often reads as padding.
- Use one column, most recent first. Some applicant tracking systems read multi-column layouts in the wrong order. List jobs and projects in reverse-chronological order (most recent first).
- Use standard section headings. Headings like "Technical Skills" are safer for applicant tracking systems and easier for recruiters to scan than "My Toolbox."
- Send a PDF unless the posting asks for another file type. A PDF keeps your layout the same on every screen.
- Name the file so a recruiter can find it. "Firstname-Lastname-Data-Scientist.pdf" is easy to spot in a folder of 200 downloads. "resume-final-v3.pdf" isn't.
If one rule feels hard, it's usually the first. Cutting your own work down to one page can feel like throwing away effort. The cut usually makes the page better, because what's left is what you'd actually want to talk about.
The plain look may also surprise you if you've browsed resume templates. Those designed layouts look great to a person and can scramble in a parser, so a plain page is the safer bet.
Contact Details and Headline
Your name, headline, and contact information should always be visible at the top of the page.
Why? You don't want a recruiter or hiring manager to have to search through the whole resume to figure out how to get in touch with you, do you? Make it easy for them.
Here are some key things to remember about the contact information on your data science resume:
- Simplify your address to just the city and state.
- List a good, working phone number and a professional-looking email address.
- Include your personalized LinkedIn URL.
- Add a GitHub link or personal profile link to your contact information, and make it clickable. Keep it in the body of the page, not the word processor's header, because some applicant tracking systems skip header content.
Your headline sits under your name. Make it the job you're looking to get, not the job you have now. If you want to become a data scientist, your headline should say "Data Scientist" even if you're currently working as a chef, for example.
That can feel like overreaching when you don't have the title yet. But a headline tells the reader which job you're applying for, and the rest of the page backs it up.
Meet Lena, Our Example Job Seeker
To make the advice concrete, we'll follow one person through the rest of this guide. Lena Okafor is fictional, but her situation may sound familiar.
She's a marketing analyst at an online store, where she has spent four years writing SQL and running campaign tests. She's now working through a data science path and has finished two projects she can explain from start to end. She wants her first data scientist role, and she's worried her experience looks like "just marketing."
You'll see her bullets, her skills block, and her full one-page resume as we go. Here's how the top of her page looks:
LENA OKAFOR
Data Scientist
Chicago, IL | lena.okafor@example.com | (312) 555-0147
github.com/[your-username] | linkedin.com/in/[your-profile]
Her headline already says where she's going. Everything below it has to show she can do the work.
How to Write Data Scientist Resume Bullets
Bullets are where most of the work happens, and they're the hardest part to write. You know you did something useful, but "worked on a model" is all that comes out.
A bullet is one line under a job or project entry. A strong line has four parts, and together they make up the bullet formula:
- An action verb that shows you did the work yourself.
- What you analyzed or built, described clearly enough to picture.
- The stack, named the way job postings name it.
- A result you can explain in an interview, like how your model did against a baseline or what your analysis recommended.
Here's how the first line of Lena's late-delivery project fits the formula:
| Part of the formula | Words from Lena's first project line |
|---|---|
| Action verb | "Trained" |
| What you built | "a gradient-boosted model … on about 96,000 public e-commerce orders to flag deliveries likely to arrive late" |
| The stack | "scikit-learn" (Python goes in the stack line above the bullets) |
| A result you can explain | "catching 71% of late orders in a held-out month, against 38% for a rule-based baseline that flagged as many orders" |
Read the finished line out loud. It sounds like a person explaining their work, not a list of keywords, and that's the effect you're after.
Your verb is the first thing a reviewer reads. Verbs like trained, tested, modeled, forecast, segmented, cleaned, measured, and automated describe data science work. Assisted, helped, and worked on only show you were nearby.
The fourth part is the hardest on a first resume, because nothing you've built has run for a company yet.
It's easy to get stuck here, and tempting to make up a business number. Don't.
You have better options, and they hold up in an interview. Here are three kinds of results you can back up:
- A baseline comparison. How your model did against a simple rule, the average, or the current method, on data it hadn't seen.
- The decision it informs. What your analysis recommends, like "don't launch the new page," and why.
- Time saved. What your work replaced, shown as a before and after you can walk through.
Of the three, the baseline is the one we'd make sure every model line has, because a score with no baseline says very little.
A model that's 95% accurate sounds strong, until you learn that about 93% of the orders in this dataset arrive on time. A model that always guesses "on time" scores almost the same. A reviewer who knows that will ask, and you want your line to have answered the question already.
Each pair below shows a common resume line, a stronger rewrite, and why the rewrite holds up in an interview.
A Model Line
Weak: Built a machine learning model to predict late deliveries with 95% accuracy.
Strong: Trained a gradient-boosted model in scikit-learn on about 96,000 public e-commerce orders, catching 71% of late deliveries against 38% for a rule-based baseline that flagged as many orders.
Why it works: Accuracy hides the problem, because most orders arrive on time. The rewrite names the data, the number that matters (the share of late orders caught), and what the model beat. Comparing at the same number of flagged orders keeps the test fair, since a model that flags every order would catch them all.
An Analysis Line
Weak: Performed A/B testing analysis using Python.
Strong: Analyzed a 290,000-user landing page A/B test in Python, found the new page's lower conversion rate wasn't statistically significant, and recommended keeping the old page.
Why it works: It names the scale, the result, and the decision. "Not significant" is a real finding, and saying so shows judgment.
It's tempting to leave a result like this off because it feels like a failure. But knowing when the data doesn't support a change is a big part of the job, and a hiring manager will recognize it.
A Line From a Non-Data Job
Weak: Responsible for campaign reporting at an online retailer.
Strong: Replaced three weekly campaign spreadsheets with one SQL and Python report, saving the marketing team about four hours a week.
Why it works: This wasn't a data science job, and the line doesn't pretend it was. It shows repeatable data work, which is the part that carries over.
If you have relevant work experience to the job you're applying for, make sure your description consists of mostly accomplishments rather than duties. Employers want to see what you actually did, not just what you were supposed to do.
Two rules keep your lines honest:
- Never invent business impact. "Increased revenue by 15%" from a portfolio project falls apart at the first follow-up question.
- Quote the score you got on your own test data. If you entered a Kaggle competition, quote your own rank or score, not the top of the leaderboard.
Both rules protect you more than they limit you. The interview is where your resume gets tested, and a line you can defend for ten minutes is worth more than an impressive one you can't.
Need projects to write about? Our list of 30 data science projects is a good place to start.
How to List Your Technical Skills
The skills section is the part of your resume an ATS cares about most, and the part a hiring manager trusts least. Your job is to satisfy the first reader without losing the second.
Recruiters and hiring managers often do a keyword search as a first step in viewing your resume. You want to make sure key terms like "Python" or "machine learning" are highlighted.
Group your skills the way a posting groups them, so a reviewer can match them line by line. Here's a layout with realistic entry-level entries. Keep only the ones your own projects use.
| Category | Realistic entry-level entries |
|---|---|
| Languages | Python, SQL |
| Data analysis | pandas, NumPy |
| Machine learning | scikit-learn, XGBoost |
| Statistics | Hypothesis testing, A/B testing, regression |
| Visualization | Matplotlib, seaborn, Tableau |
| Tools | Git, Jupyter, Docker |
It's tempting to fill every row and add a few more for good measure. Resist that, because every entry is a promise that you can talk about it.
Follow these rules when you fill in the table:
- Match the posting's exact wording. If it says "machine learning," don't write only "ML." List whichever the posting names.
- Only list what you've used and can explain. Every tool you list invites a question. More on this below.
- Show your most important skills in a line. The skills the posting cares about most should also appear in a project or job line, so the keyword and the proof sit on the same page.
- Skip skill bars, star ratings, and percentage charts. Many applicant tracking systems can't read them, and a reviewer can't check them.
- Put your strongest skills first, and keep each row to three or four entries. List your strongest and most relevant skills first. Leave skills where you're less comfortable or that are less likely to be relevant to the position for later in your list.
Rule 3 is the one we'd spend the most time on. A skills block on its own is a claim. When the same skill shows up in a project line, the claim comes with evidence, and a reviewer can see both without hunting.
Large language models (LLMs) and generative AI show up in more postings now. List them only when a project uses them, like a small app that answers questions about a set of documents. A line that shows what you built carries more weight than the keyword alone.
Watch Out for Skills You Can't Explain
Rule 2 is the one hiring teams test. And they test it in conversation, which is exactly where a padded skills list comes apart.
"I think a huge red flag is putting too many technologies on [a resume] and then not being able to back them up, especially in a phone call," Clay McLeod told us when he managed bioinformatics software development at St. Jude Children's Research Hospital.
Stephanie Leuck was a university recruiting manager at 84.51° when we spoke with her, seeing thousands of entry-level data science resumes a year. She echoed this sentiment.
"Make sure [the skills you list on a resume] are skills that you can actually speak to. If you read a book once about R, but you can't actually code in R and you've never coded in R, don't list R as one of your skills. Only put skills on there that you can speak to."
A shorter list you can defend beats a longer one you can't. If you're unsure about a skill, ask yourself whether you could explain your last use of it to a stranger for five minutes.
Keep Soft Skills Out of the List
Should you include soft skills here? Probably not. Recruiters tend to scan this section looking for the specific technical skills they need. Stating that you're skilled in "communication" or a "team player" isn't going to help your resume stand out.
It's better to show that you have these skills in the project and work experience sections. Here, you can highlight the ways your "soft" and "hard" skills have functioned together to produce meaningful results.
Soft skills still matter. A line about what you did is simply a better place to show them than a list.
How to Present a Data Science Project
If you don't have a data science job yet, your projects are doing the job of your work history. That puts a lot of weight on two or three entries, so it's worth getting them right.
Employers want to see what you can actually do with the skills you list. That might be data analysis projects, machine learning projects, or even published scientific articles or coding tutorials.
Many data science employers will look at your project portfolio. They want to see how often you build things and what kinds of projects you take on.
That's why your GitHub link belongs at the top of the page. A reviewer who opens it should find the projects your resume describes, each with a README.
Showcase Relevant Projects
When you choose which projects to highlight, focus on relevance. Pick only the projects that fit the job you're applying for.
Data science work exists to answer real questions, whether they come from a business, a research team, a hospital, or a public agency. A hiring team cares less about how hard the technique was than about whether it answered a question someone would ask.
That can sting if your proudest project is technically impressive but answers nothing in particular. It's still worth keeping, and it's often easy to fix by reframing it around a question.
How many projects should you list? Two or three. Format each one like a job entry, with a name, a stack line, dates, two or three lines, and a repo link.
Two finished projects look better than six half-finished notebooks. If you have more, pick the ones closest to the posting and leave the rest on GitHub, where a curious reviewer can still find them.
Need help putting together projects for your resume and portfolio? We have a whole series of blog posts to guide you through building great data science projects. Plus, the next chapter in this guide discusses what projects you should showcase in a job application and how.
What Makes a Project Stand Out
Picture a reviewer opening two repos in a row. Both use the same dataset and the same library.
One has a notebook of charts. The other starts with a question and ends with an answer. The second one gets the call.
Five details separate a data science project from a notebook:
- A question someone would ask. "Which orders are likely to arrive late?" gives a reviewer something to discuss. "Exploring an e-commerce dataset" doesn't.
- Data you collected or cleaned yourself. Any data you've worked with that required you to build spreadsheets/data tables yourself counts. Examples of this could be working with videos, posts, blogs, customer reviews, and audio. Experience working with unstructured data is impressive. It shows you're capable of doing unique work with messy data, not just crunching numbers in pristine datasets.
- A baseline and the right metric. Show what your model beat, and choose a metric that fits the problem.
- A recommendation. End with what someone should do, based on what you found.
- A README that reproduces the result. Someone else can install your project and get your numbers.
You don't need all five on day one. If we had to pick two to add first, they'd be the question and the baseline, because those are what a reviewer will ask about.
Leave off tutorial projects you didn't change, like the Titanic or iris datasets done exactly as taught. Leave off notebooks that look at data but don't answer a question.
Highlight Your Skills
Be as specific as possible about the skills, tools, and technologies you used in each project. Specify the coding language and the libraries you used. Talk about how you created the project, and in the case of group projects, point out your individual contribution.
Show Communication Through Your Work
Earlier, we said to keep soft skills like communication out of your skills list. This is where they show up instead, inside the way you describe your work.
Data science recruiters are looking for people who have the technical skills that they need, sure. But they also want people who are effective communicators and who understand the big picture. They want data scientists who can effectively tell stories with data.
One way you can demonstrate these traits is by highlighting collaborative projects. This proves you can work and communicate with a team.
Another way is to tie each result to the question it answers. This shows you understand how your work helps solve bigger problems.
Write your projects and work experience sections with these ideas in mind. Here's one complete project entry from Lena's resume, as it appears on the page:
Late Delivery Prediction | Apr 2026 - Jun 2026
Python, pandas, scikit-learn | github.com/[your-username]/late-delivery-model
- Trained a gradient-boosted model in scikit-learn on about 96,000 public e-commerce orders to flag deliveries likely to arrive late, catching 71% of late orders in a held-out month, against 38% for a rule-based baseline that flagged as many orders.
- Built features from seller location, product weight, and promised delivery date in pandas, and kept only the ones that improved results on a validation set.
- Wrote a one-page summary recommending which sellers to contact first, and documented how to rerun the model in the README.
The last line shows communication without ever using the word.
Your repo does as much work as the line on your resume. Our guide to building and presenting your data portfolio covers what else to include.
How to Tailor Your Resume to the Role
Tailoring sounds like a lot of extra work, especially when you're sending many applications. It doesn't have to be, and it pays off.
Tailoring your resume takes more upfront work than the copy-paste approach. But adding small details here and there in accordance with the specific job will earn you points.
Does that mean you need to do a wholesale rewrite every time you apply for a job? No. But, at a minimum, look for important keywords and skills mentioned in the job posting and be sure to include those on your resume.
Start by working out which kind of data scientist the posting wants. The title is the same, but the jobs differ, and that can catch you off guard.
| Role type | What postings ask for | What to lead with |
|---|---|---|
| Product or analytics data scientist | SQL, experiments, metrics, working with stakeholders | An A/B test or analysis that ends in a recommendation |
| Machine learning data scientist | Python, scikit-learn, model evaluation, sometimes deployment | A model compared with a baseline, with code a reviewer can run |
| Research-leaning data scientist | Statistics depth, published work, often a graduate degree | Publications and the methods behind them |
The posting's list of duties tells you which one it is. If it mentions experiments and working with other teams, it's closer to product. If it mentions training, deploying, or monitoring models, it's closer to machine learning.
Once you see the difference, reading postings gets easier. You'll also start to notice which type suits your background, which is useful for more than your resume.
You don't need a separate resume for each. Keep one master version, then reorder your projects and skills for each application. Once you have a master version, that can take ten minutes rather than an evening.
If you're applying for your dream job, you can take things up a notch. Look at the company's website to get a feel for its style and tone, then adjust the wording of your summary to match. Keep the layout plain, so an applicant tracking system can still read it.
Moving Into Data Science From Another Job
If you're coming from another career, you might feel like you're starting from zero. You're usually not. Most jobs leave you with something that carries over, and the trick is knowing what to put in front.
A first data scientist role is often a move from a nearby job, like data analysis, software development, or research. Plenty of people come from somewhere else entirely. Your background decides what you lead with.
| Coming from | What carries over | What to lead with |
|---|---|---|
| Data analysis | SQL, business questions, stakeholder work | An analysis that ended in a decision, plus any modeling you added |
| Software development | Python, Git, testing, APIs | A model wrapped in code someone else can run |
| Academia or a PhD | Statistics, research design, writing | Publications, rewritten so a business reader sees the question and the result |
| A non-technical job | Knowledge of an industry | Projects that use data from that industry |
Don't underrate the last row. If you spent years in logistics, healthcare, or retail, a project built on that industry's data lets you talk about the problem like an insider, and that's hard for other applicants to match.
Say what you're moving into in your summary. Lena's starts with "Marketing analyst moving into data science." That tells a reviewer how to read the rest of the page.
Reframing changes which parts of a real job you highlight. It never changes your job title. If your official title was Marketing Analyst, it stays Marketing Analyst.
That line matters more than it might seem. A background check or a single reference call can surface a changed title, and it would undo all the trust the rest of your page built.
Thinking about a data analyst role first? Our data analyst resume guide covers that resume. Coming from data engineering? Our comparison of data science and data engineering shows how the two jobs differ.
Writing the Job Entries
Each work experience entry should include the following:
- your job title
- the company
- the period of time you held the position
- your accomplishments in that role
If your work experience is not relevant to the job you're applying for, then you'll still want to list it. But, you only need to include a company name, your job title, and the dates worked. You don't need to take up space with all the details of an irrelevant job.
How Far Back to Go, and What to Do About Gaps
How far should you go back? That depends. Ten to 15 years is a common limit, but if you have relevant work experience that goes back further than that, you may want to include it.
A gap in your work history is common, and you don't need to hide it. Explain it in one line, so a reviewer doesn't have to guess.
For example, if you took two years off to raise children between 2015 and 2017, you still want to add those dates on your resume. Simply state that you were a stay-at-home parent during that period.
A gap often worries the person who has it more than the person reading about it. One honest line is usually all it takes.
Education, Certifications, and Extras
Education sits near the bottom of an entry-level data science resume, and that's often a relief to career changers. It still needs to be right, because some roles filter on it.
List only degrees from after high school, such as community college, college, and graduate degrees. If you studied without finishing a degree, you can still list it with the credits you earned, like "Completed 60 credits toward a BA in Economics, 2019–2021."
What if your degree is not relevant to the job you're applying for? You should still list it. Some positions simply require a degree in any field, so you want to ensure you're in the running for these positions.
Some data scientist roles ask for a graduate degree. The Bureau of Labor Statistics notes that data scientists typically need at least a bachelor's degree, but some jobs require a master's or doctoral degree.
Read how the posting phrases it. If a master's is listed as preferred rather than required, it can still be worth applying.
| What you have | What to do |
|---|---|
| A finished degree, in any field | List it, with the year if it's recent |
| A degree you didn't finish | List the credits you earned and the years you attended |
| A degree from 15 or more years ago | List it, and decide whether to show the year |
| High school only | Leave the Education section off |
| A certificate or path you're working on | List it under training, marked "in progress" |
Certificates and Training
Finally, list relevant "micro-degrees," online training certifications, and other professional training here.
Data science certificates like those offered through Dataquest are great to add here. That's because they can show recruiters targeted skills. Plus, Dataquest paths include skills-based projects that you can also include on your resume.
A certificate on its own tells a reviewer you studied. The projects you built along the way show what you learned, so give those the space on the page.
Before you pay for a certification, compare the data science certifications worth holding.
Older Degrees and High School
If the graduation date for your degree is 15+ years back, use your discretion about whether you want to include a date or not. Some reviewers may use an old graduation date to guess your age.
If you don't have a degree, don't sweat it. Just leave the Education section completely off of your resume. What you don't want to do is list your high school information. This is another red flag for recruiters and hiring managers.
When to Add an Extras Section
If you have room, add an "Extras" section. You can call it Awards, Competitions, or Community.
In data science, you have a few options for this section. You might list good Kaggle competition results or meetups and events you've joined. Anything else that shows you're actively involved in learning and doing data science is also fair game.
Data science and machine learning hackathons can help on your resume. They let recruiters know you can enhance your skills and knowledge while creating actual content and projects.
Treat this section as the last thing you add. If it pushes you onto a second page, it's the first thing to cut.
A Complete Entry-Level Data Scientist Resume Example
Here's everything above on one page. This is Lena's full resume, the one we've been building toward.
Her day job already includes some SQL and testing work. Her page shows how to use that kind of experience without making it sound bigger than it is. If your past job has nothing like it, use the same layout with a shorter experience section.
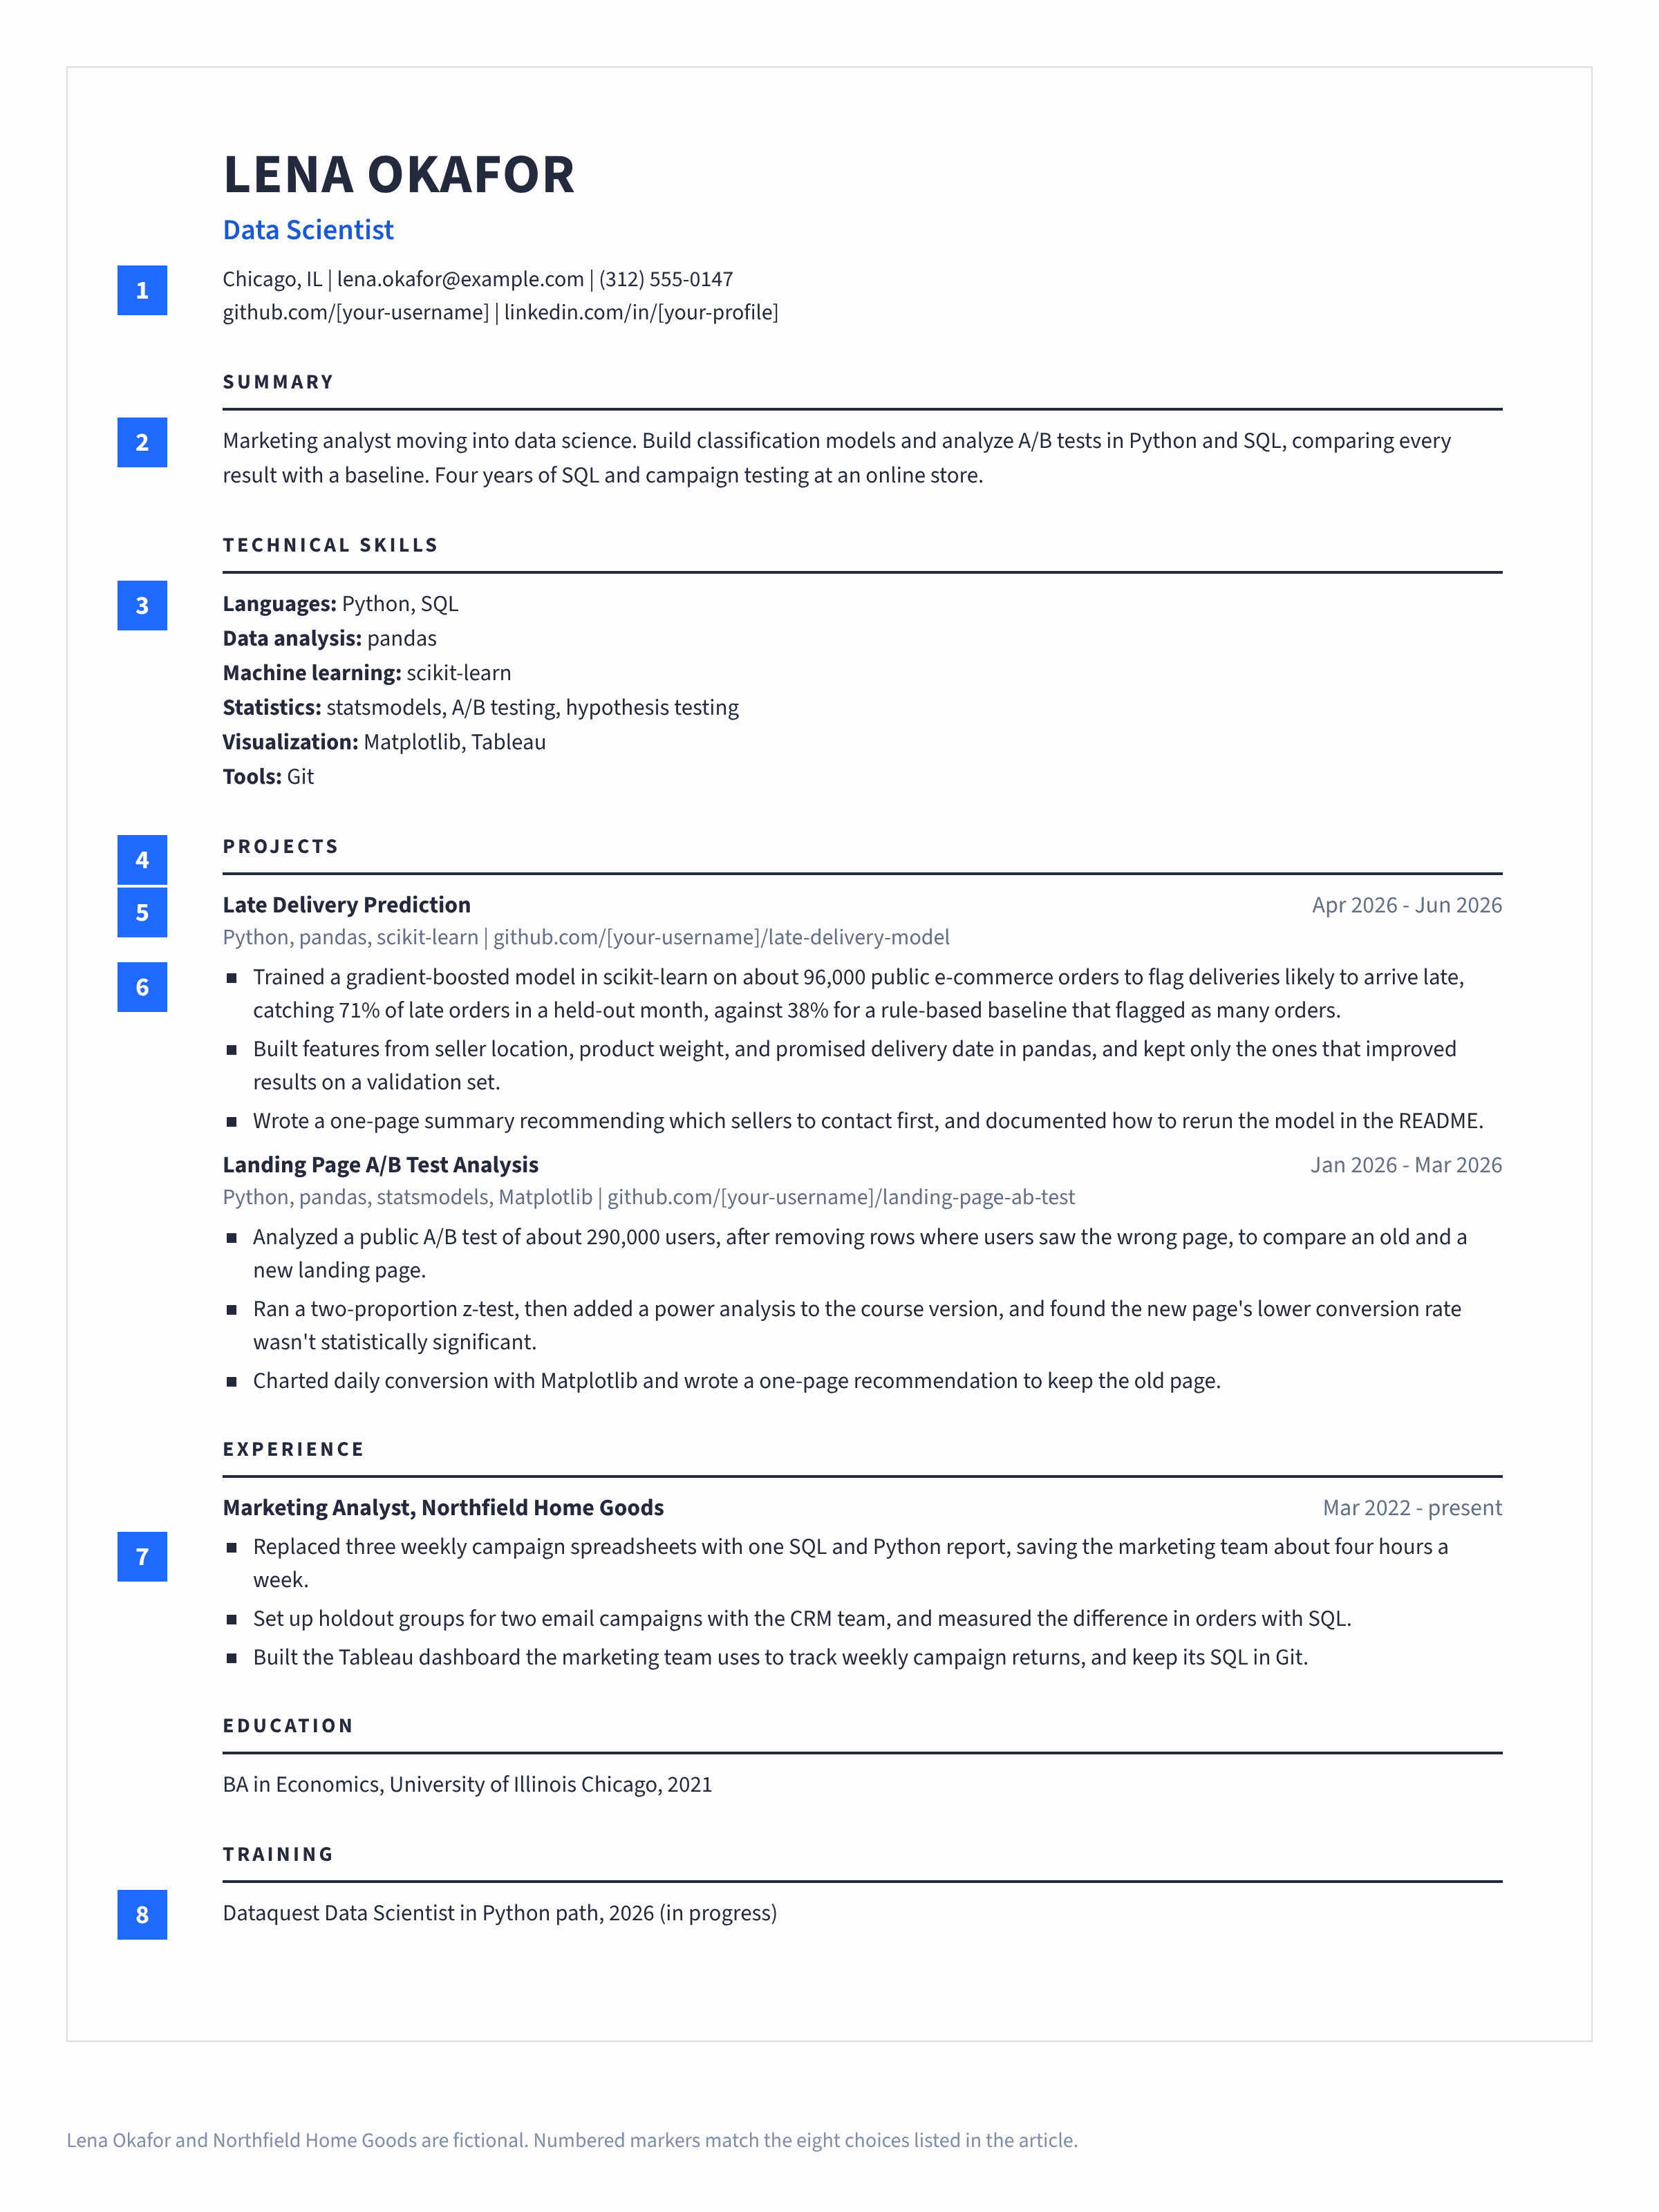
Take a minute with it before you read the notes below. Try to spot the choices for yourself, then check them against this list. Eight choices on that page are worth naming:
- The GitHub link sits in the contact details at the top. It stays out of the word processor's header, because some applicant tracking systems skip header content.
- The headline says "Data Scientist," and the summary states the move. A reviewer knows how to read the page before reaching the projects.
- Her key skills show up in a project or job line. Nothing important in the skills block is there just for the keyword match.
- Projects sit above experience. Her job shows SQL and testing, but her modeling work, the core of the roles she wants, is in her projects. So her projects lead.
- Each project has a repo link, a stack line, dates, and a question it answers. A reviewer can open each one and ask about it.
- Every result comes with a baseline or a decision. No line claims revenue or business impact she can't show.
- The job lines lead with SQL and testing work. Her title stays Marketing Analyst.
- The path is marked "in progress," and education and training sit last. That's where a reviewer expects them on an entry-level page.
The page also uses one column and standard section headings, and it fits on one page. An applicant tracking system can read every line.
What we like most about Lena's page is how little it tries to impress. Every line is modest and checkable, and that's what makes the whole page convincing.
Common Data Scientist Resume Mistakes
Many of these mistakes come from good intentions, like wanting to look more experienced or not wanting to leave anything out. Check your resume for these eight before you send it:
| Mistake | Why it hurts, and what to do instead |
|---|---|
| Typos and spelling errors | Many recruiters read a typo as a lack of care. Check your spelling and grammar, as covered below |
| No projects, and no data science work to show | A reviewer has nothing to judge your data science skills by. If your work history doesn't already show that work, build two projects before you apply |
| An accuracy score with no baseline | "95% accurate" means little alone. Say what a simple guess would score |
| A key skill you list but never show | A reviewer may think you've only read about it. Name it in the line where you used it, or remove it |
| A tutorial project you didn't change | It only shows you followed along. Change the question, the data, or the method, and lead with that change |
| Invented business impact | Revenue or cost figures from a portfolio project fall apart in an interview. Use results you can show |
| Two pages with no data science job history | One page is plenty. Trimming to fit usually makes the page better |
| A multi-column or heavily designed template | Some applicant tracking systems read columns in the wrong order. Use one plain column |
If you only fix one thing on this list, make it the baseline. It's quick to add, and it changes how a reviewer reads every number on your page.
Polish With Finishing Touches
When your content is in place, the last big step is a spelling and grammar check. A huge red flag for recruiters and hiring managers is a resume with spelling or grammar errors.
Recruiters often get hundreds of applications for one entry-level job. They look for quick reasons to narrow the pile.
Although it might seem minor, a simple typo suggests a lack of attention to detail. Believe it or not, that's enough for some recruiters to toss out your resume regardless of the skills and experience you have.
So make sure your writing is clear and free of errors. A friend who edits well can check it for you, and apps like Hemingway and Grammarly can also help you clean up and simplify your writing.
Be careful not to put too much trust in automated grammar-check software. Even the best apps make mistakes.
One more trick that works well is to read your resume out loud, slowly. Your ear catches what your eye skips, especially on a page you've read twenty times.
What to Do Next
You now have everything you need to write the page. The hardest part is usually the first draft, so write a rough one today and improve it from there.
If you've rewritten the same line three times and still have nothing to explain, build another project. That usually means the page needs more evidence, and more evidence is something you can go and get.
Use the first line of Lena's late-delivery project as the model for each new line you add:
Trained a gradient-boosted model in scikit-learn on about 96,000 public e-commerce orders to flag deliveries likely to arrive late, catching 71% of late orders in a held-out month, against 38% for a rule-based baseline that flagged as many orders.
Of course, a resume doesn't mean much if you can't prove you've got the skills it lists. In the next chapter, we're going to take a deeper look at what kinds of projects you should be doing, and how you should be highlighting them in your portfolio.
When you're ready to add the next project to your page, try our Data Scientist in Python path. It includes 27 projects, with courses covering Python, SQL, statistics, and machine learning.
Frequently Asked Questions
How do I write a data scientist resume with no experience?
Put your projects above your work experience, and make every claim something a reviewer can check. Name the dataset, the tools, and the question each project answers. Compare every model with a baseline. Link to repos that have a README, and use only numbers your own work produced.
How long should a data scientist resume be?
One page, for most people applying for entry-level roles or changing careers. If yours runs longer, cut coursework you haven't used first. Then cut early jobs with no data work, then lines that repeat the same skill.
Do I need a cover letter for a data scientist job?
Send one when the posting asks for it or gives you a place to add it. Keep it to three short paragraphs. Name the role you want, the one project that best matches the posting, and why you want to work there. Don't repeat your resume line by line.
Should I put my GitHub or Kaggle profile on my resume?
Yes, if they show finished work. Pin the two or three repos your resume links to, and give each a one-line description. A Kaggle profile helps when it shows competitions or notebooks you can explain.
Before you send anything, search your commit history for API keys and passwords. Deleting a key from your code doesn't remove it from old commits in a public repo. If you find one, change the key first, then remove it from the history.
Can a data analyst become a data scientist?
Yes, and it's a common route. You already know SQL, business questions, and how to present results. Add Python modeling and statistics, then build projects that end in a prediction or an experiment, not only a dashboard.
Do I need a master's degree or PhD to be a data scientist?
Not for every role. Most data scientist jobs ask for at least a bachelor's degree, and research-leaning roles ask for a graduate degree most often. Product and analytics roles weigh projects and experience more.
Can I list a course project on my resume?
Yes, if you can say what you did beyond the brief. A guided project you extended with new data, a new question, or a better model is your project, and the line should lead with the part you added. A project you finished exactly as written belongs under training as coursework.
Is it okay to use AI to write my data scientist resume?
Yes, as long as the final page is still yours. A first draft from an AI tool can get you past the blank page, and it can check your work too. Ask it to list skills in your skills block that no line mentions, and numbers you couldn't explain.
Then do three things before you send it. Verify every fact and number, and never keep one the tool added. Rewrite anything that doesn't sound like you. And make sure you can defend every claim, because a sentence you wouldn't say in an interview doesn't belong on the page.
Is a data science CV different from a resume?
It depends on where you apply. In much of Europe and in South Africa, "CV" is simply another word for resume. In the US and Canada, a CV is usually a longer academic record used for research and teaching roles. For most entry-level data scientist jobs in the US, a one-page resume is what employers expect.
This article is part of our in-depth Data Science Career Guide.
- Introduction and Table of Contents
- Starting Your Career in Data Science: What Are Your Options?
- How and Where to Find Data Science Jobs
- How to Write a Data Science Resume — You are here.
- How to Create a Data Science Project Portfolio
- How to Fill in Application Forms, When to Apply, and Other Considerations
- Preparing for Job Interviews in Data Science
- Assessing Data Science Job Offers and Negotiations